96GB max RAM · 5 bays · 10GbE
AINAS Score 62
No verified UK price
View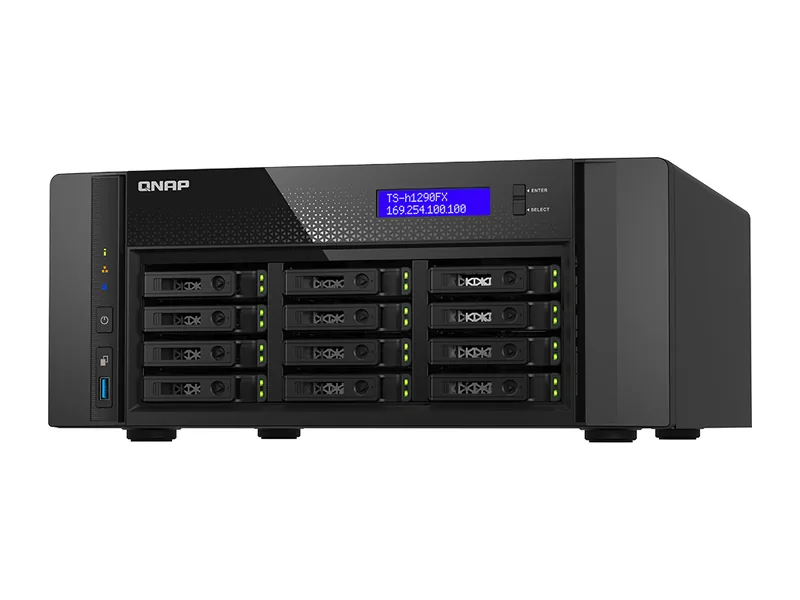
Can the QNAP TS-h1290FX run local AI?
Yes. AMD EPYC 7232P (or 7252) on 64G model; EPYC 7302P on 128G/256G models, backed by a 1024GB memory ceiling, lets the QNAP TS-h1290FX handle 70B class models at higher-quality quantization, or large mixture-of-experts models at 4-bit (Estimated).
A graphics card can be added through its Full-size GPU, which is the biggest single speed upgrade for local models.
Local LLM support is documented by the manufacturer.
The TS-h1290FX is QNAP's all-flash twelve-bay server, and the same chassis that underpins the QAI-h1290FX. Out of the box it is a storage system, but with an EPYC CPU, up to 1TB of ECC memory and four PCIe Gen4 slots it can host large local models once you add a GPU.
QNAP's own guide for on-premises RAG with Qsirch recommends this model with an RTX 6000 Ada or RTX 4000 Ada, and its LLM tools run models such as DeepSeek R1 distils and Gemma 3. Without a GPU it can still run models on the CPU, but the point of buying it for AI is the slots.
The entry version uses an 8-core EPYC 7232P with 64GB; the 128GB and 256GB versions move to the 16-core 7302P. Two 25GbE ports and twelve U.2 bays mean it can feed a busy team. It is the better buy than the QAI version if you already own suitable GPUs or want to choose your own.
Amazon UK
TS-h1290FX-7302P-128G
£10,614.20
Verified
In stock
View dealProduct prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon.co.uk at the time of purchase will apply to the purchase of this product.
Each capability shows how it was confirmed: Verified by AINAS, Vendor confirmed, Community confirmed or Unverified.
| Capability | Supported | Evidence | Note |
|---|---|---|---|
| Local LLM | Yes | Vendor confirmed | QNAP on-prem Qsirch RAG guide recommends TS-h1290FX with RTX 6000 Ada or RTX 4000 Ada; LLM Core runs local models (DeepSeek R1, Gemma3, gpt-oss 20B etc). Needs an add-in GPU for useful speed. |
| Ollama | Yes | Vendor confirmed | QNAP Ollama tutorial: Container Station 3+, x86_64, 16GB+ RAM for 7B; optional NVIDIA GPU in Container Station mode. |
| Open WebUI | Yes | Vendor confirmed | QNAP Open WebUI tutorial: QTS 5.2 / QuTS hero h5.2 or later with Ollama on the same NAS. |
| RAG | Yes | Vendor confirmed | On-prem Qsirch RAG via LLM Core on QuTS hero 5.2.1+, model named in guide. |
| AI search | Yes | Vendor confirmed | Qsirch AI Semantic Search requires 64-bit x86, QTS/QuTS hero 5.0.1+, 8GB RAM. AI Mode (x74 series or above, 16GB+ VRAM GPU) eligibility for this model not stated. |
| GPU expansion | Yes | Vendor confirmed | Official GPGPU list up to RTX 4000 Ada 20GB and RTX 5060 Ti 16G; RTX PRO Blackwell cards are listed for QAI-h1290FX but not this model. |
| Hardware acceleration | Limited | Vendor confirmed | No integrated GPU; hardware transcoding via listed NVIDIA cards; Coral Edge TPU (4 TOPS) on AI accelerator list. |
| AI photos | Yes | Vendor confirmed | QuMagie AI-assisted photo management listed. |
| AI video | Limited | Vendor confirmed | QVR Face listed under QTS QVR Pro only. |
| Surveillance AI | Yes | Vendor confirmed | QVR Surveillance 2 free + 6 on registration; QVR Pro 8 free channels (QTS). |
Out of the box the TS-h1290FX has 64GB; the official ceiling is 1024GB of DDR4 ECC RDIMM with ECC support. A memory upgrade is the cheapest way to make it more useful for AI.
Working backwards from 1024GB: reserve about 8GB for the operating system and storage services, and at roughly 0.6GB per billion parameters at 4-bit, the largest model that fits is around 1693B (Estimated).
ECC memory support is a plus for always-on systems that also hold important files.
It can. A 4x PCIe Gen4 (slot 1 x16, slot 2 x16, slot 3 x8, slot 4 x16); slots 3 and 4 take cards up to 280 mm is the route, and a card with 16GB or more of its own memory changes what the TS-h1290FX can run. Measure the space and check the 750W power budget before ordering.
Yes. Retrieval augmented generation keeps your documents on the NAS and feeds the relevant passages to a local model. The TS-h1290FX has the memory for an embedding model alongside a chat model, and 12 bays for the library. Support is documented by the manufacturer.
The manufacturer also provides AI search across your files (documented by the manufacturer), which covers simple document questions without setting up your own stack.
Built-in networking: 2 x 25GbE + 2 x 2.5GbE. Plenty for a shared knowledge base with several users.
| Configuration | RAM | SSD | Notes |
|---|---|---|---|
| TS-h1290FX-7232P-64G | 64GB | None | EPYC 7232P (or 7252), 8 cores; 8 x 8GB memory |
| TS-h1290FX-7302P-128G | 128GB | None | EPYC 7302P, 16 cores; 8 x 16GB memory |
| TS-h1290FX-7302P-256G | 256GB | None | EPYC 7302P 16C/32T; 8 x 32GB. Not found on UK store. |
The closest QNAP model by AINAS Score. Only the specifications that differ are listed.
Its strongest AINAS profiles are Home Lab at 82 and RAG at 79, which points to home lab owners who want one box for storage, containers, media and a few AI services.
Other AI Ready systems closest in price.
Yes. Ollama support is documented by the manufacturer. See the capability table above for the source.
Yes. Open WebUI support is documented by the manufacturer. See the capability table above for the source.
Yes. AI photos support is documented by the manufacturer. See the capability table above for the source.
Yes. Surveillance AI support is documented by the manufacturer. See the capability table above for the source.
Partly. Hardware acceleration support is documented by the manufacturer. See the capability table above for the source.
It has 2 x 25GbE + 2 x 2.5GbE built in, and the 4x PCIe Gen4 (slot 1 x16, slot 2 x16, slot 3 x8, slot 4 x16); slots 3 and 4 take cards up to 280 mm can take a faster network card. The fastest port is 25GbE.
Every field records its source. Specifications were last checked on . Spot an error? Send a correction with a manufacturer link.