64GB max RAM · 8 bays · 2.5GbE
AINAS Score 58
No verified price
AI ReadyQNAP
Why AI Ready: 12th Gen Core i5-12400 or i3-12100, no NPU, PCIe Gen 4 x16 GPU path limited to low-profile cards up to the 6GB RTX 3050, 64GB memory ceiling, and QNAP does not position it for local AI.
Updated
Can the QNAP TVS-h674 run local AI?
Only lightly. Expect 32B class models comfortably, and 70B class models at 4-bit with little headroom (Estimated) on the QNAP TVS-h674: Intel Core i5-12400 (Core i3-12100 on i3-16G) does the work with up to 64GB of memory, which is fine for experiments rather than a daily assistant.
Its PCIe x16 slot leaves room to add a GPU when you outgrow CPU inference.
Local LLM support is documented by the manufacturer.
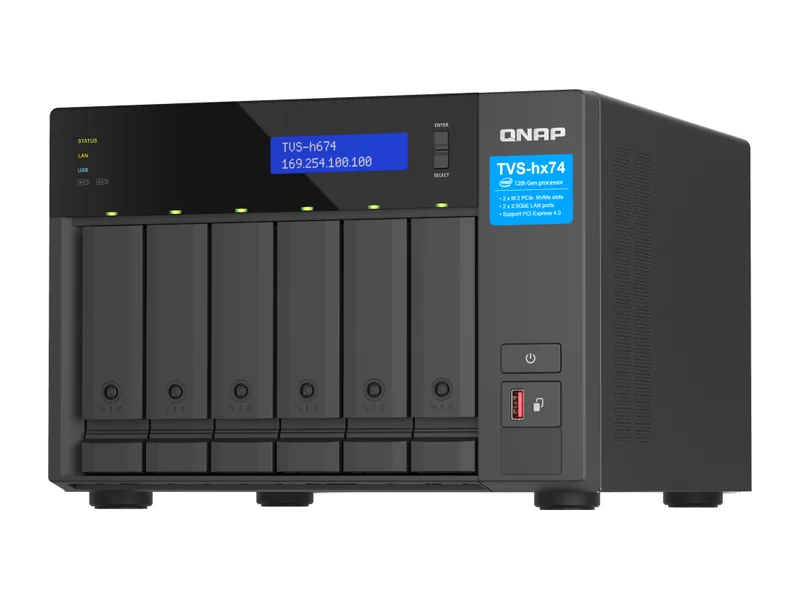
The TVS-h674 suits a buyer who wants a six-bay QNAP tower that can also host local models in containers. It has an Intel Core i5-12400 with 6 cores, 32GB of DDR4 SODIMM memory that expands to 64GB, and two 2.5GbE ports. It also has 2 M.2 slots and a PCIe Gen 4 x16 slot for a GPU. Docker and virtual machines are supported, and QNAP's Ollama and Open WebUI guides apply to it (Vendor confirmed). The memory estimates are generous: Llama 3.3 70B fits at Q4 (Estimated). The AINAS Score is 58.
The main limit is the GPU path. The x16 slot only takes cards up to 185mm, and the listed GPUs top out at a 6GB RTX 3050 LP and a 4GB RTX A400. Buyers who want fast inference on larger models, or QNAP's Qsirch AI Mode, will be held back, because that mode needs a GPU with 16GB or more of VRAM and none is listed. Those buyers should look for a system with a full-length GPU slot, room for a card with 16GB or more of VRAM, and a power supply larger than 250W. Check the memory ceiling too, since 64GB is the maximum here.
Amazon UK
TVS-h674-i3-16G
No current price
Checked , no price yet
Out of stock
Buy on AmazonProduct prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon.co.uk or Amazon.com, as applicable, at the time of purchase will apply to the purchase of this product.
Each capability shows how it was confirmed: Verified by AINAS, Vendor confirmed, Community confirmed or Unverified.
| Capability | Supported | Evidence | Note |
|---|---|---|---|
| Local LLM | Limited | Vendor confirmed | QNAP Ollama guide applies (x86_64, 16GB or more for 7B models, GPU optional and must be in Container Station mode). Largest listed GPU is the 6GB RTX 3050 LP, and the i3-16G leaves little headroom. |
| Ollama | Yes | Vendor confirmed | QNAP Container Station Ollama tutorial for QTS and QuTS hero on x86_64. |
| Open WebUI | Yes | Vendor confirmed | QNAP Open WebUI tutorial, QTS 5.2 or QuTS hero h5.2 or later. |
| RAG | Limited | Unverified | Qsirch lists on-premises RAG with no model named. Not confirmed for this model. |
| AI search | Yes | Vendor confirmed | Qsirch AI Semantic Search: 64-bit x86, 5.0.1 or later, 8GB RAM. AI Mode needs an x74 or newer NAS with a 16GB or larger VRAM GPU; none is on this model's GPU list. |
| GPU expansion | Limited | Vendor confirmed | PCIe Gen 4 x16 slot, 185 mm card limit, 250W PSU. GPU list tops out at RTX 3050 LP 6GB and RTX A400 4GB. |
| Hardware acceleration | Yes | Vendor confirmed | UHD Graphics 730; Coral Edge TPU and Hailo-8 on the AI accelerator list; listed GPUs support Hardware Transcoding. |
| AI photos | Yes | Vendor confirmed | QuMagie listed on QTS and QuTS hero. |
| AI video | Yes | Vendor confirmed | QVR Face listed under QTS only. QNAP lists this model in its AI Video Analytics navigation group. |
| Surveillance AI | Yes | Vendor confirmed | QVR Surveillance 2 free channels plus 6 on registration; QVR Pro 8 free channels (QTS only). |
Calculated from the TVS-h674's memory and each model's published size at each quantization. Rows marked Estimated are calculations, not benchmarks. Check any model.
| Model | Best quantization | Runs? | Memory needed | Expected performance | Verification |
|---|---|---|---|---|---|
| Llama 3.2 3BLlama, 3.21B | Q8 | Yes | 13GB | Not measured | Estimated |
| Llama 3.1 8BLlama, 8.03B | Q8 | Yes | 19GB | Not measured | Estimated |
| Qwen3 8BQwen, 8.19B | Q8 | Yes | 19GB | Not measured | Estimated |
| Gemma 3 12BGemma, 11.8B | Q8 | Yes | 24GB | Not measured | Estimated |
| Qwen3 14BQwen, 14.8B | Q8 | Yes | 28GB | Not measured | Estimated |
| Phi-4 14BPhi, 14.7B | Q8 | Yes | 28GB | Not measured | Estimated |
| Mistral Small 3 24BMistral, 23.6B | Q8 | Yes | 38GB | Not measured | Estimated |
| Gemma 3 27BGemma, 27B | Q8 | Yes | 44GB | Not measured | Estimated |
| Qwen3 30B A3BQwen, 30.5B | Q8 | Yes | 47GB | Not measured | Estimated |
| Qwen3 32BQwen, 32.8B | Q8 | Yes | 50GB | Not measured | Estimated |
| DeepSeek-R1 32B (Qwen distill)DeepSeek, 32.8B | Q8 | Yes | 50GB | Not measured | Estimated |
| Llama 3.3 70BLlama, 70.6B | Q4 | Yes | 60GB | Not measured | Estimated |
| Llama 4 Scout 17Bx16ELlama, 109B | None fits | No | 89GB at Q4 | Not measured | Estimated |
| Qwen2.5 72BQwen, 72.7B | Q3 | Yes | 54GB | Not measured | Estimated |
| Mistral Large 2 123BMistral, 123B | Q2 | Yes | 62GB | Not measured | Estimated |
One verdict per workload, from the TVS-h674's use-case scores and capability rows. Unknown means we cannot confirm it, not that it probably works.
The TVS-h674 is a good fit for local LLM work. Ollama is Vendor confirmed through Container Station, though local LLM support is marked limited, and Llama 3.3 70B fits at Q4 in 64GB (Estimated).
Private RAG is an OK fit, not a confirmed one. Open WebUI and Ollama are Vendor confirmed, but the Qsirch on-premises RAG row is Unverified and names no model for this system.
AI search is an OK fit. Qsirch AI Semantic Search is Vendor confirmed and needs 8GB of RAM, but AI Mode needs a GPU with 16GB or more of VRAM and none is on this system's list.
AI photos is an OK fit. QuMagie is listed on both QTS and QuTS hero and is Vendor confirmed, so the photo features are covered by the vendor's own software.
Surveillance is an OK fit. QVR Surveillance gives 2 free channels plus 6 on registration, and QVR Pro gives 8 free channels on QTS only (Vendor confirmed).
Home lab use is an OK fit. Docker and virtual machines are both supported, and the system has six bays, 2 M.2 slots and two 2.5GbE ports for storage and services.
Business use is an OK fit. It has six bays, a 3 year warranty and a choice of QTS or QuTS hero, but memory is non-ECC and networking stops at 2.5GbE.
Creative AI is a good fit on paper. The PCIe Gen 4 x16 slot is Vendor confirmed but limited to 185mm cards, with a 6GB RTX 3050 LP the largest listed GPU, and hardware acceleration is supported.
Plan on upgrading. 32GB is fitted as standard, while the TVS-h674 accepts 64GB of DDR4 SODIMM, which is the difference between models up to the 14B class, with 32B class models a tight fit and 32B class models comfortably, and 70B class models at 4-bit with little headroom (Estimated).
Our estimate for the biggest model that fits in 64GB is about 93B parameters at 4-bit, after setting aside 8GB for the system. Long context windows reduce that figure (Estimated).
Yes, through a 2x PCIe Gen 4: slot 1 x16, slot 2 x4; cards up to 185 x 111.15 x 18.76 mm. That is the single biggest upgrade for local AI on the TVS-h674: model layers move into fast graphics memory and replies speed up dramatically. Card size and power are the constraints (250W supply).
As the storage half of a RAG setup it works well; as the model host it is limited. Small embedding models run fine on the TVS-h674, while the answering model needs more compute than it has.
The manufacturer also provides AI search across your files (documented by the manufacturer), which covers simple document questions without setting up your own stack.
For network access it has 2 x 2.5GbE. Enough for light use; large imports will take a while.
| Configuration | RAM | SSD | Notes |
|---|---|---|---|
| TVS-h674-i3-16G | 16GB | None | Core i3-12100 4C/8T, 16GB. |
| TVS-h674-i5-32G | 32GB | None | Core i5-12400 6C/12T, 32GB. |
The closest QNAP model by bay count and AINAS Score. Only the specifications that differ are listed.
Best fit: people who want a private chat assistant or coding model at home without sending data to a cloud service. That is where the TVS-h674 scores highest (Local LLM 60/100), followed by RAG (59/100).
Less suited to teams moving large files over the network every day.
Other AI Ready systems closest in overall score.
Workloads it suits
Yes at Q4, but only just, and not at Q8. Llama 3.3 70B needs 43GB at Q4, which fits within the 64GB maximum (Estimated). At Q8 it needs 75GB, so it does not fit (Estimated). Qwen2.5 72B is marginal at Q4 (Estimated). Llama 4 Scout 17Bx16E does not fit at Q4 (Estimated). These are calculations, not benchmarks.
Yes. It ships with 32GB of DDR4 SODIMM and the maximum is 64GB. The i3-16G configuration has 16GB. The memory is not ECC, so it will not correct errors. Extra memory raises the size of model that loads, but the listed GPUs have 6GB of VRAM at most.
Yes, with limits. It has a PCIe Gen 4 x16 slot that takes cards up to 185 x 111.15 x 18.76mm, powered by a 250W supply. QNAP's GPU list tops out at a 6GB RTX 3050 LP and a 4GB RTX A400. QNAP names no larger cards. The second slot is Gen 4 x4.
Yes, it has 2 M.2 slots alongside its six drive bays. The record does not say whether they are meant for caching or for storage pools, so check QNAP's specification page before planning a layout. The system also has two 2.5GbE ports.
Two. The TVS-h674-i5-32G has an Intel Core i5-12400 with 6 cores and 12 threads and 32GB of DDR4 SODIMM, and the TVS-h674-i3-16G has a Core i3-12100 with 4 cores and 8 threads and 16GB. Both take up to 64GB and share the six bays, 2 M.2 slots, PCIe Gen 4 x16 slot and 250W power supply. QNAP's notes say the i3-16G leaves little headroom for local models, so the i5-32G is the one to pick for Ollama work.
Yes. Docker is supported, and virtual machines are as well. QNAP's Container Station guides for Ollama and Open WebUI apply to this system (Vendor confirmed). It runs QTS 6.1.0 or QuTS hero h6.1.0, and the i3-16G configuration leaves little headroom for local models.
Yes. Ollama support is documented by the manufacturer. See the capability table above for the source.
Yes. Open WebUI support is documented by the manufacturer. See the capability table above for the source.
Yes. AI photos support is documented by the manufacturer. See the capability table above for the source.
Yes. Surveillance AI support is documented by the manufacturer. See the capability table above for the source.
Yes. Hardware acceleration support is documented by the manufacturer. See the capability table above for the source.
It has 2 x 2.5GbE built in, and the 2x PCIe Gen 4: slot 1 x16, slot 2 x4; cards up to 185 x 111.15 x 18.76 mm can take a faster network card. The fastest port is 2 x 2.5GbE.
Every field records its source. Specifications were last checked on . Spot an error? Send a correction with a manufacturer link.