Why does memory matter most?
A language model has to sit in memory to run. Its size depends on the number of parameters and the quantization: at 4-bit, a model needs roughly 0.6GB per billion parameters. The NAS operating system, storage services and other apps need memory too, and longer conversations need extra for context.
How big are popular models?
These are the download sizes of the default 4-bit (Q4_K_M) tags in the Ollama library, and the total system memory we recommend to run each on a NAS (Estimated):
| Model | Size at 4-bit | Recommended NAS memory |
|---|---|---|
| Llama 3.1 8B | 4.9GB | 14GB |
| Qwen3 8B | 5.2GB | 15GB |
| Gemma 3 12B | 8.2GB | 18GB |
| Qwen3 14B | 9.3GB | 20GB |
| Gemma 3 27B | 17GB | 29GB |
| Qwen3 32B | 20GB | 32GB |
| Llama 3.3 70B | 43GB | 60GB |
Our recommendation is the 4-bit size multiplied by 1.2 for context and runtime, plus 8GB for the NAS itself.
Can you upgrade memory later?
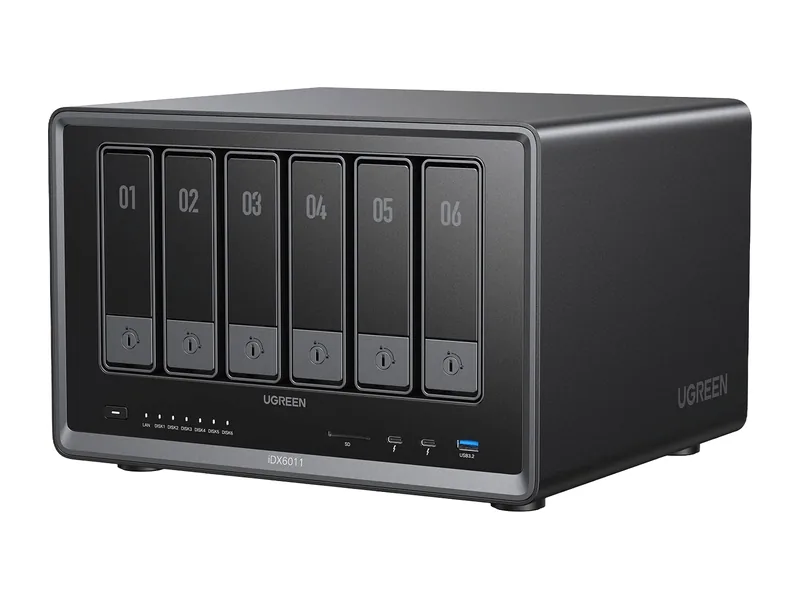
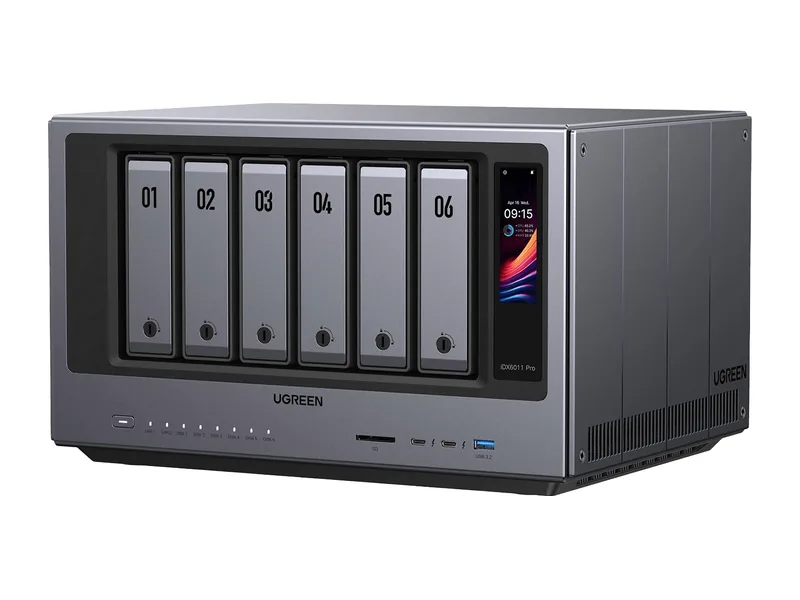
It depends on the system. Many AI NAS models use standard SO-DIMM slots: the Minisforum N5 Pro, NIMO Nexus Pro and Zettlab Ultra models accept up to 96GB. Others solder memory to the board: UGREEN's iDX6011 range is sold with 32GB or 64GB and cannot be upgraded. Mainstream NAS units often ship with 4GB or 8GB but accept 32GB or 64GB.
What else uses memory on an AI NAS?
The operating system and storage services need a few gigabytes, more with ZFS or caching enabled. Docker apps add their own share: a media server, photo recognition and Open WebUI each take hundreds of megabytes to a few gigabytes. An embedding model for document search takes 1GB to 2GB on top of the chat model. That is why we add 8GB to every model figure above rather than matching memory to model size exactly.
Does more memory make models faster?
No. More memory lets larger models fit. Speed depends on memory bandwidth, the processor and above all whether a graphics card runs the model.
Common questions
Is 32GB enough for a home AI NAS?
For a private assistant with 8B to 14B class models, yes. For 32B class models, aim for 64GB.
What about GPU memory?
With a graphics card, the model needs to fit in the card's memory to run at full speed. System memory still matters for everything else.
Does memory speed matter?
Yes, for speed rather than for which models fit. Generating each word reads the whole model from memory, so faster memory and more memory channels give quicker answers. That is one reason systems with fast soldered memory can feel quick, even though they cannot be upgraded.